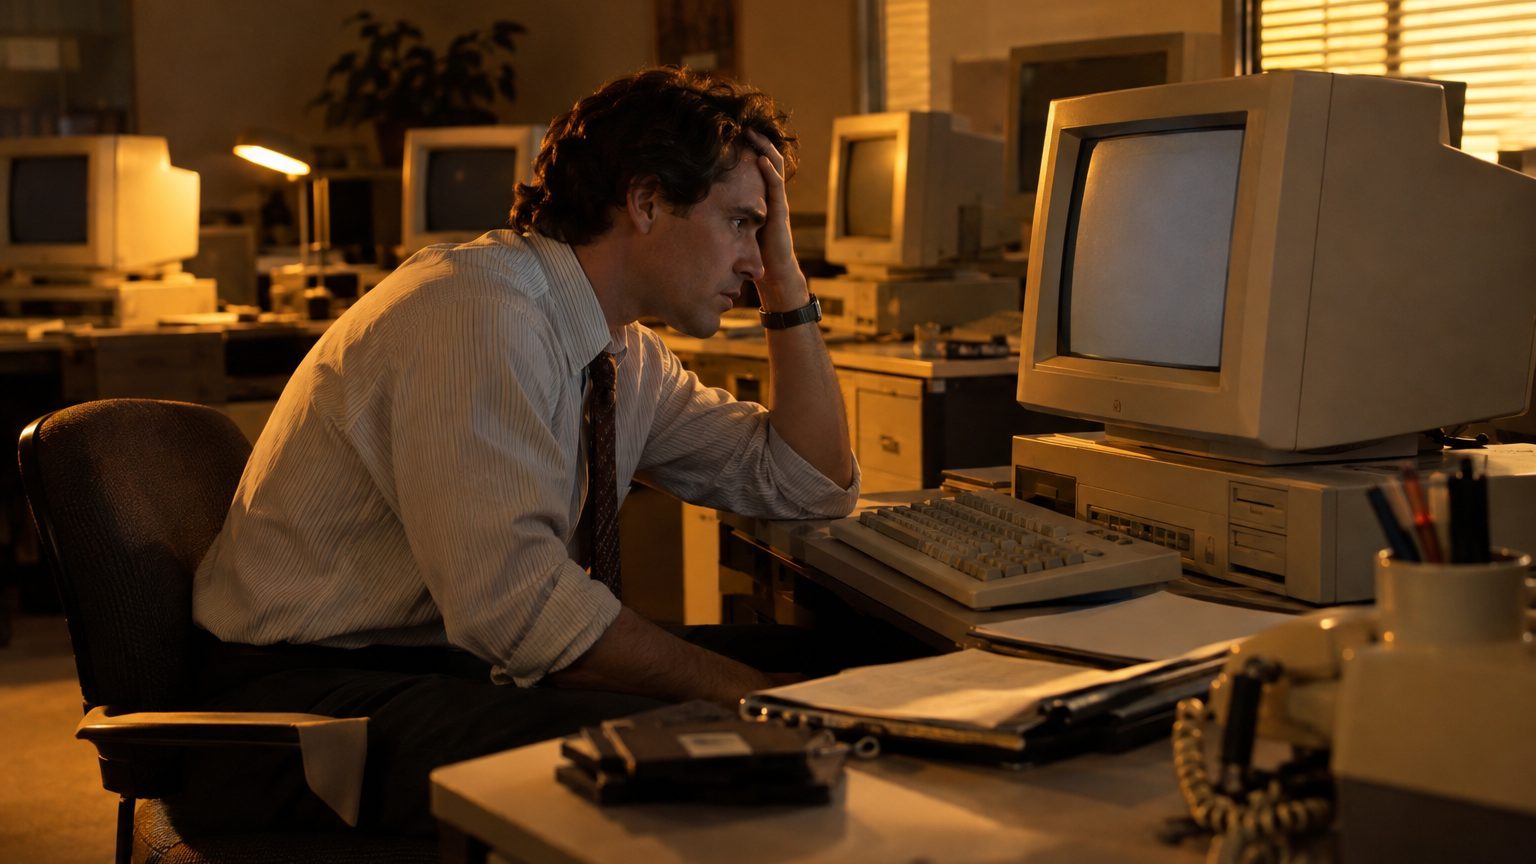
That morning, screens stopped responding. In several American university and military computer centers, network administrators found machines frozen, unable to execute a single command. No one yet understood what was happening.
Phone lines began ringing from one building to another. No explanation circulated, only identical symptoms everywhere: extreme slowness, followed by complete lockup.
- A program designed to count computers on a network self-replicated uncontrollably in November 1988.
- The rate at which the code reinstalled itself was too high, causing dozens of copies on each machine simultaneously.
- The absence of a central defense mechanism and standardized protocols amplified the network saturation.
- This inadvertent outage led to the creation of computer incident response teams.
A program designed to count, not to harm
At the heart of this quiet panic, an American student wrote, in November 1988, a program capable of copying itself from machine to machine across the network. The aim wasn’t to destroy anything: he simply wanted to estimate how many computers were interconnected at the time. To propagate, his program exploited vulnerabilities already known to system administrators, without needing to force open any doors. Once installed on one machine, it took the opportunity to knock on the door of the next, and so on.
Nothing in this concept foreshadowed disaster.
The tweak that tipped everything over
What brought the network to its knees wasn’t a vulnerability exploited for mischief, nor a desire to cause harm. It was a design detail that sent things off course. To prevent an already infected machine from detecting the program and blocking subsequent copies, the student had planned for it to reinstall itself from time to time, even on systems that were already affected.
The rate chosen for these reinstallations turned out to be far too high. Each machine ended up executing dozens of copies of the program at the same time, each trying in turn to spread elsewhere.
Saturation followed almost immediately.
A network that did not know how to defend itself
The late-1980s network had simply not been designed to withstand such a surge. The machines comprising it operated on a principle of mutual trust, with each computer accepting connections from elsewhere without much suspicion. No central mechanism monitored abnormal behavior on a large scale, and no standardized procedure existed to isolate a malfunctioning machine from the rest of the system quickly. Faced with the silent multiplication of copies, administrators had no protocol to follow, only their own judgment and improvised phone exchanges.
Everyone discovered the problem on their own, unaware that other sites were experiencing the exact same situation at the same moment. Coordination at a national level simply did not exist yet.
What the outage gave rise to
The episode marked a discreet yet lasting turning point in the history of networked computing. In the months that followed this widespread saturation, specialized teams emerged with the sole mission of responding to computer incidents at their earliest signs. These incident-response teams would later become a model adopted by many countries and institutions, far beyond the university circle where it all began.
What the student had imagined as a simple technical census thus became, without his intention, one of the starting points of organized cybersecurity as we know it today. The outage was not an act of sabotage: it arose from a poorly calibrated figure in a line of code, proof that a global network can falter for a reason small enough to fit on a Post-it note.